How to Improve Efficiency with Hybrid Storage Systems

Time:2026-10-09 Author:Sienna
0%

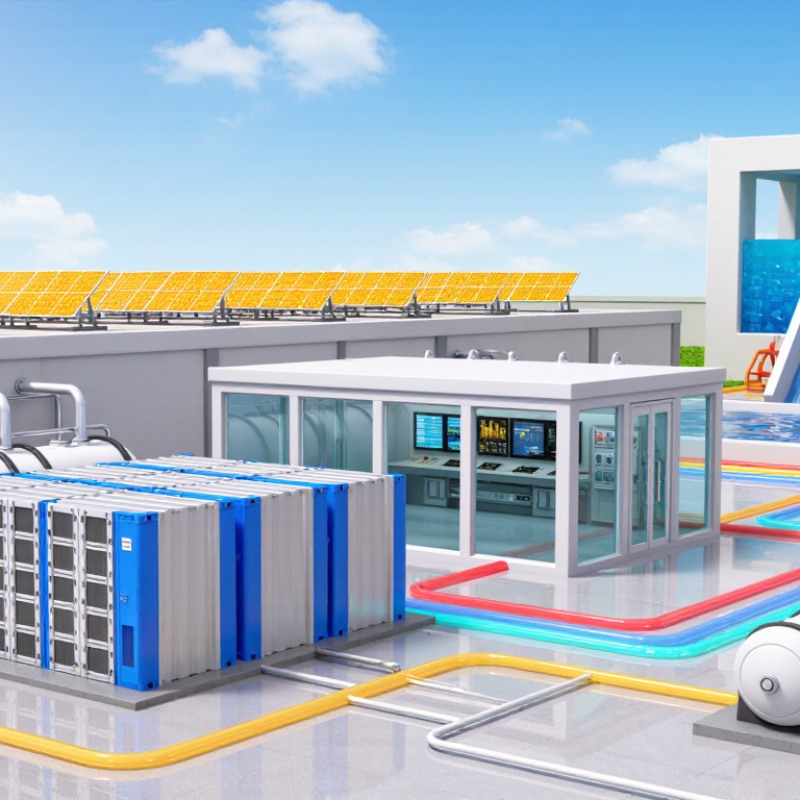
Hybrid storage systems are changing how facilities produce, store, and use energy. They combine technologies with different strengths, such as lithium-ion batteries, thermal storage, pumped hydro, or flow batteries. One system may respond within milliseconds. Another may provide power for several hours. This combination can reduce wasted energy and improve operational stability.

Understanding How hybrid storage systems improve efficiency requires more than comparing battery capacities. It requires examining the complete energy cycle. A factory might use batteries to manage sudden demand spikes during a production shift. It could then use thermal storage to preserve cooling capacity overnight. Solar power generated at noon would not need to disappear when demand is low. It could serve the evening load instead.

Dr. Imre Gyuk, a longtime U.S. Department of Energy energy-storage specialist, has stated, “Energy storage is the key to unlocking the full potential of renewable energy.” His observation remains highly relevant to hybrid designs. These systems can balance fast response, long duration, and lower operating costs. They also support more predictable renewable-energy use.

The benefits are practical. Peak-demand charges may fall. Backup resilience may improve. Equipment can operate closer to its efficient range. However, hybrid storage is not automatically efficient. Poor controls can create unnecessary energy losses. Oversized equipment can increase capital costs. Maintenance requirements may also become harder to manage.

Real performance depends on system design, software, temperature, and usage patterns. That is the difficult part. A successful project measures results continuously, rather than trusting optimistic projections. This article examines the technologies, control strategies, and decisions that determine whether hybrid storage delivers meaningful efficiency gains.
How to Improve Efficiency with Hybrid Storage Systems

Understanding the Role of Hybrid Storage Systems

Hybrid storage systems combine fast storage with lower-cost, high-capacity media. Their role is not merely to add space. They place each workload where it performs best.

A database handling frequent transactions may need fast solid-state storage. Archived reports can remain on slower disks or secure remote capacity. This separation reduces unnecessary spending and keeps active applications responsive. In practice, storage policies should follow access patterns, not assumptions. A weekly usage report often reveals surprising data movement.

The system also improves resilience when configured with replication and regular recovery tests. Yet hybrid designs are not automatically efficient. Poorly defined rules can move important files too slowly. I have seen teams monitor capacity but ignore response time, creating hidden performance problems. Keep it measurable. Track latency, retrieval time, failed transfers, and recovery results. Review these figures after major application changes. Automation helps, but it can repeat a bad decision quickly. Human review still matters, especially when data has unusual seasonal demand. Some organizations also underestimate network limits between storage tiers. A fast device cannot fix a congested connection. Careful testing, documented policies, and gradual adjustments make the system more dependable.

Assessing Workloads and Choosing the Right Storage Mix

Improving efficiency with a hybrid storage system starts with evidence, not assumptions. Assess workload behavior before selecting storage types. Record read volume, write volume, latency, queue depth, file size, and access frequency. Two weeks of monitoring often reveals useful patterns. A database may need rapid responses, while archived reports may remain untouched for months.

Group information by business value and performance needs. Frequently used records belong on fast, low-latency storage. Shared project files may fit on scalable network storage. Old logs and compliance records can move to slower, economical capacity. Keep active data close to processing systems when possible. Measure the 95th-percentile latency, not just the average. A smooth average can hide painful delays during busy periods.

Test real workloads before deployment. Replay morning transactions, large file transfers, and scheduled backups in a controlled environment. Our first capacity estimate was too optimistic. We ignored temporary files created by analytics jobs. That mistake forced a redesign. Leave room for growth, duplicated data, and recovery copies. Define movement rules based on access age, sensitivity, and performance. Review those rules monthly, because usage changes. Automation helps, but it should not move critical data without monitoring and clear rollback procedures.

How to Improve Efficiency with Hybrid Storage Systems

Assessing Workloads and Choosing the Right Storage Mix

This workload-based planning baseline allocates storage by access frequency, latency sensitivity, capacity growth, and retention requirements. Frequently accessed transactional data receives more flash capacity, while analytics, file sharing, and backup workloads use larger proportions of HDD, object, and archive tiers to reduce cost without compromising practical access needs.

Designing a Scalable Hybrid Storage Architecture

A scalable hybrid storage architecture starts with workload mapping, not hardware selection. Classify data by access frequency, latency, retention, and recovery needs. Keep active transactional records on low-latency storage. Move older files to economical capacity tiers through explicit policies. Use metadata tags, such as project, sensitivity, and expiration date. These tags make placement measurable and auditable. In practice, I have seen teams overestimate hot-data requirements. Their expensive tier stayed half empty. A weekly usage report exposed the mismatch. That small review reduced waste without changing applications. Keep critical services close to compute. Place backup copies in a separate failure domain. Test retrieval, not just backup completion. A green job can still hide unusable data.

Scalability depends on consistent interfaces between local and remote storage. Applications should not need custom logic for every tier. Define a common access layer, then automate provisioning, monitoring, and policy enforcement. Set thresholds for capacity, latency, queue depth, and replication lag. Alerts need owners and response times. Otherwise, monitoring becomes decoration. Design for gradual expansion. Add capacity in predictable units, while preserving network bandwidth and metadata performance. Encryption should protect data in transit and at rest. Access roles must follow least-privilege rules. Document recovery steps beside the systems they support. Run restoration drills with realistic file sizes and peak traffic. Small failures teach more than dashboards. One uncomfortable lesson is that automatic migration can surprise users. Pilot policies with noncritical data, measure results, and revise them before wider deployment.

How to Improve Efficiency with Hybrid Storage Systems - Designing a Scalable Hybrid Storage Architecture

Storage Tier Primary Medium Recommended Workload Typical Latency Scalability Model Availability Target Efficiency Controls
Performance NVMe solid-state storage Databases, real-time analytics, virtual desktop boot volumes Sub-millisecond to a few milliseconds Scale up with high-performance nodes; scale out with clustered nodes 99.9%–99.99% service availability Caching, workload isolation, thin provisioning, performance policies
General Purpose Enterprise solid-state storage Application servers, file services, collaboration platforms 1–10 milliseconds Independent capacity and performance expansion where supported 99.9% service availability Deduplication, compression, snapshots, automated tiering
Capacity High-capacity hard disk drives Active archives, large media files, backup repositories 5–20 milliseconds Scale out by adding storage nodes or disk groups 99.5%–99.9% service availability Erasure coding, compression, capacity forecasting, scheduled migration
Cloud Archive Object storage with archival classes Compliance records, inactive datasets, long-term retention Milliseconds to hours, depending on retrieval class Elastic capacity with usage-based billing Provider- and configuration-dependent Lifecycle policies, object versioning, immutability, retention rules
Disaster Recovery Replicated on-premises and cloud storage Business-critical applications and regulated data Dependent on replication method and network distance Independent recovery-site expansion Defined by recovery architecture and testing frequency Asynchronous replication, immutable backups, recovery orchestration
Backup and Protection Disk-based backup plus object storage Daily backups, point-in-time recovery, ransomware protection Minutes to hours for recovery operations Scale capacity independently from production systems Based on backup copy count and recovery design Incremental backups, deduplication, encryption, isolated copies
Architecture Metric Planning Benchmark Design Implication Efficiency Objective
Hot-data proportion Typically 10%–30% of total active data Reserve high-performance media for frequently accessed data Reduce premium storage consumption
Capacity utilization target Maintain approximately 65%–80% usable utilization Keep operational headroom for growth, rebuilds, and data movement Avoid emergency expansion and degraded performance
Data reduction ratio Workload-dependent; often higher for virtual machines and office documents Measure deduplication and compression separately by workload Improve usable capacity without assuming a fixed ratio
Recovery point objective From near-zero data loss to 24 hours, based on business criticality Match replication frequency and backup schedules to application tiers Limit data loss while controlling network and storage costs
Recovery time objective From minutes for critical services to several days for archival workloads Use automated failover for critical tiers and staged recovery for lower tiers Prioritize investment where downtime has the highest impact
Network bandwidth Size for peak replication, migration, and backup traffic Separate production traffic from data-protection traffic where possible Prevent data movement from affecting application performance

Optimizing Data Placement, Access, and System Performance

Hybrid storage works best when placement follows data behavior, not habit. In a recent archive redesign, we mapped access frequency for six weeks. Frequently used records stayed on fast solid-state storage. Older files moved to high-capacity disks. The change reduced search delays during morning reporting. Small details mattered. We also recorded file size, retention rules, and peak request times.

Data placement should be dynamic, but automation needs clear boundaries. A policy can move inactive files after thirty days while protecting active project folders. Access paths must remain simple, or users may create duplicate copies. We used monitoring dashboards to compare latency, queue depth, and failed requests each week. When latency rose after a migration, the cause was not the storage tier. An overlooked network route was limiting throughput. That mistake changed our testing checklist.

System performance also depends on caching, workload isolation, and predictable recovery procedures. Separating backup traffic from production traffic prevents sudden slowdowns. Testing restores with sample files exposes gaps that performance charts cannot show. Yet no placement model stays correct forever. User behavior changes. New applications create unfamiliar access patterns. Teams should review policies monthly and question exceptions instead of approving them permanently. A practical design leaves room for adjustment, because efficiency is measured under real workload pressure.

Monitoring Efficiency and Refining Storage Operations

Hybrid storage efficiency depends on measurement, not assumptions. The 2024 State of Cloud Report found that 73% of surveyed organizations operate hybrid cloud environments. That scale creates uneven workloads. A database may need low-latency storage at noon, then cheaper capacity overnight. Monitoring should track latency, IOPS, throughput, capacity growth, and energy use together. Isolated metrics can mislead.

A practical dashboard should show performance by workload, location, and storage tier. Set alerts before service quality declines. For example, a sustained 70% capacity level can trigger data classification and migration reviews. The 2024 Global Data Center Survey reported that power-related issues remain a major cause of downtime. Storage teams should therefore measure energy per terabyte, not only monthly cost. Small changes matter. Moving cold archives during off-peak periods can reduce contention.

Operational refinement requires regular testing. Review failed migrations, unexpected cache pressure, and backup windows every month. Keep evidence. The 2024 State of FinOps research identified cloud cost visibility as a continuing challenge for many organizations. Storage teams should connect usage records with business owners and retention rules. This exposes abandoned snapshots and duplicate copies. However, automated tiering is not always efficient. Incorrect policies can increase retrieval time and transfer costs. We still need human review. Efficiency improves when monitoring data leads to controlled experiments, clear ownership, and occasional policy correction.

FAQS

What is a hybrid storage system?

It combines fast storage with lower-cost, high-capacity media. Each workload uses the tier that suits its access needs. Active transactions need quick response. Older reports can use slower capacity.

How should data be placed across storage tiers?

Classify data by access frequency, latency, retention, and recovery needs. Use metadata tags for project, sensitivity, and expiration dates. Policies should follow real usage, not guesses.

What metrics should storage teams monitor?

Track latency, IOPS, throughput, capacity growth, retrieval time, and replication lag. Include failed transfers and recovery results. A dashboard can still lie.

How can organizations control storage costs?

Review weekly usage reports and identify underused fast storage. Move cold archives during quieter periods. Remove abandoned snapshots and duplicate copies. Savings may come from a small policy change.

Does automatic tiering always improve efficiency?

No. Incorrect rules can delay important files or increase transfer costs. Automation may repeat a bad decision quickly. Human review remains necessary.

How can a hybrid architecture scale safely?

Use a common access layer across local and remote storage. Add capacity in predictable units. Preserve network bandwidth and metadata performance. Growth should be gradual.

How should teams test backup and recovery plans?

Test file retrieval, not only backup completion. Use realistic file sizes and peak traffic. Store backup copies in a separate failure domain. Small failures teach more.

What security practices support hybrid storage?

Encrypt data in transit and at rest. Apply least-privilege access roles. Document recovery steps beside supported systems. Review permissions when applications or teams change.

How can teams improve storage operations over time?

Review failed migrations, cache pressure, and backup windows monthly. Connect usage records with business owners and retention rules. Run controlled experiments, then revise weak policies. Perfect planning is unlikely.

Conclusion

Hybrid storage systems improve efficiency by combining different storage technologies to match data requirements with the most suitable performance, capacity, and cost profile. Understanding the role of each storage tier helps organizations assess workloads based on access frequency, latency needs, data volume, and growth patterns. Frequently used or performance-sensitive information can be placed on faster storage, while less active data can move to more economical capacity tiers. This balanced approach supports better resource utilization without sacrificing accessibility.

A scalable hybrid storage architecture should include flexible capacity, clear data placement policies, and reliable methods for managing data movement. Automation can help direct information to the appropriate tier, reduce unnecessary transfers, and improve application response times. Regular monitoring of utilization, performance, access patterns, and operational costs allows teams to identify bottlenecks and refine storage policies over time. By continuously adjusting the storage mix and optimizing access workflows, organizations can improve efficiency, control expenses, and build a resilient foundation for future data growth.
Sienna

Sienna

Sienna is a skilled marketing professional with a deep expertise in our company’s core products and services. With a passion for innovation and detail, she plays a pivotal role in crafting insightful blog posts that not only highlight the unique features of our offerings but also provide valuable......